Up to 20 Seconds, Multi-Shot
A single prompt can carry an entire sequence: Flux 3 chains multiple shots into up to 20 seconds of continuous story, keeping characters, lighting and pacing coherent from cut to cut.
Flux 3 is Black Forest Labs' multi-modal AI model for video, image and audio. Its Tryonr API is not connected yet, so you can create in the live Seedance 2.0 workbench on this page while we prepare the integration.
Flux 3 coming soon · Seedance 2.0 live on this page
Flux 3 generation is not connected yet, so the full workbench below runs the real Seedance 2.0 model without sending you to another page. We will connect Flux 3 here as soon as its API is available.
Every video generated below is created, priced and labeled as Seedance 2.0 — never as Flux 3. There is no hidden model substitution.
Generate a 4–30 second video with synchronized audio from a prompt
Be specific about motion, camera angles, lighting, and mood for best results
1080p is currently available only for Standard text-only generation.
Fire and keep creating — up to 3 videos can generate at once.
Enter a prompt or upload an image and click Generate
Enter Prompt
Describe your video or upload an image
Customize
Set duration, resolution, and more
Generate
AI creates your video with audio
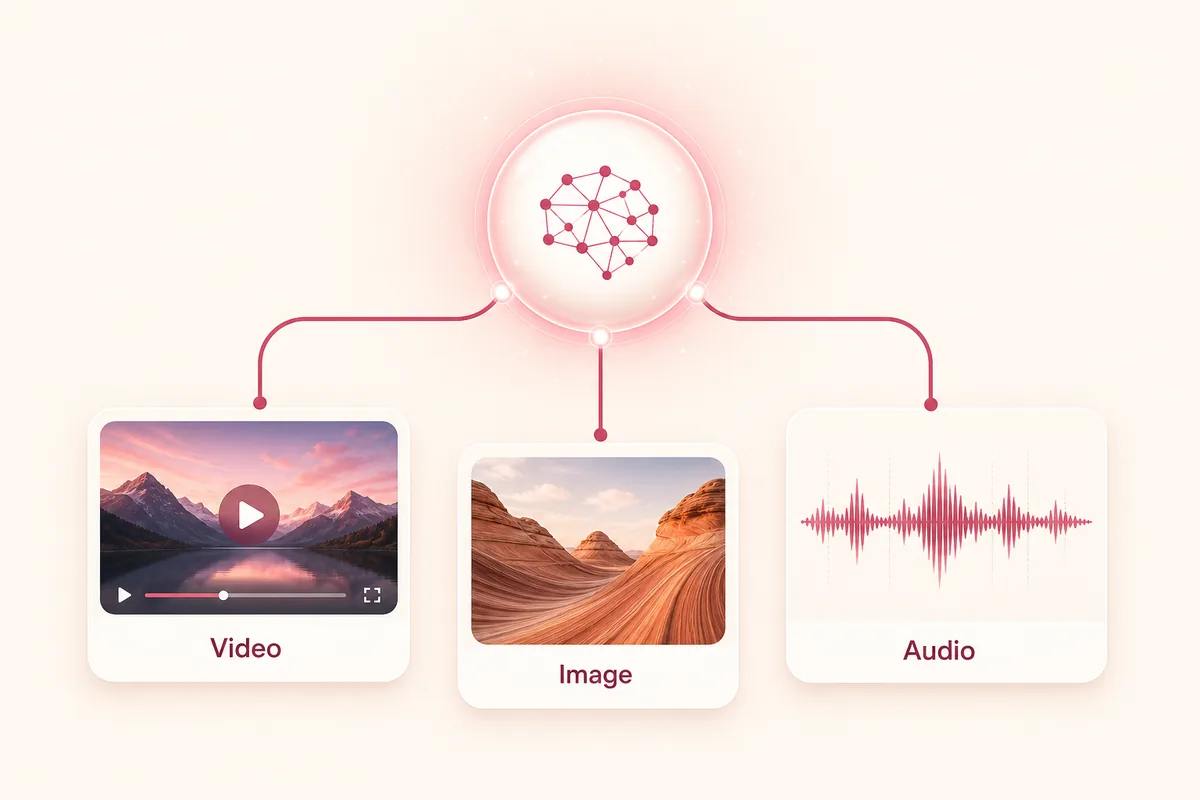
Flux 3 is the next-generation AI model from Black Forest Labs (BFL), the research lab behind the FLUX image family. Unlike earlier releases that focused on still images, Flux 3 is trained as one unified architecture for image, video, audio and action prediction — a single model that understands a scene, how it moves and how it sounds.
Announced on July 23, 2026, Flux 3 marked BFL's move into generative video. Early testers describe creations that are truer to life in every kind of style, with the fine detail — skin texture, natural motion, coherent lighting — that makes an AI video read as real footage.
Because Flux 3 is jointly trained across modalities, the same prompt can drive a still frame, a moving shot or synchronized sound. That is a different approach from pipelines that stitch separate models together, and it is why Flux 3 dialogue scenes stay lip-synced and physical actions look grounded.
Flux 3 video is in early access now. Black Forest Labs opened the first wave on July 23, 2026, and has been widening access through partner platforms and time-limited public previews since. A full public release date has not been announced yet — this page tracks the rollout as it happens.
Early access clips show what the model can hold in one generation: up to 20 seconds of multi-shot video from a single prompt, characters who speak with generated dialogue, and period-accurate footage that looks pulled from an archive.
Access currently flows through Black Forest Labs' own early-access program and short public previews hosted by partners. Spots have been limited and time-boxed, which is exactly why it pays to have your prompt ready before a window opens.
Tryonr is preparing Flux 3 generation for launch. Until it opens, use the complete Seedance 2.0 generator embedded on this page — every output is clearly labeled with the model that made it.
What early access shows the model does best — and what it means for your videos.
A single prompt can carry an entire sequence: Flux 3 chains multiple shots into up to 20 seconds of continuous story, keeping characters, lighting and pacing coherent from cut to cut.
Flux 3 generates speech, ambience and sound effects together with the picture. Testers report natural dialogue from prompts as vague as a single topic — no separate audio pass, no manual syncing.
From photoreal footage to stylized animation, Flux 3 keeps the small details honest: believable skin, fabric and light, and period-accurate texture that makes historical scenes feel archival.
The FLUX family is known for following instructions closely, and Flux 3 continues it: complex scene descriptions, camera direction and mood cues land in the output instead of getting lost.
Use the live Seedance 2.0 workbench here today; Flux 3 will replace it when the API opens.
Describe your video in the live workbench on this page — scene, subject, camera and mood.
Pick duration, generation mode, resolution, aspect ratio, audio and batch size in the embedded Seedance 2.0 generator.
Generate without leaving the page. Results are labeled Seedance 2.0; we will switch this workbench to Flux 3 as soon as its API is available.
Where BFL's new model stands next to its predecessor and today's leading video generators.
| Feature | Flux 3 | Flux 2 | Seedance 2.5 | Kling 3 |
|---|---|---|---|---|
| Modalities | Video, image, audio | Image only | Video | Video |
| Max clip length | 20s multi-shot | — | 30s single shot | 10s |
| Native audio | Yes, with dialogue | No | Not announced | Not announced |
| Stands out for | Realism & dialogue | Still-image quality | 4K single-shot length | Motion control |
| Status | Early access | Available | Rolling out | Live on Tryonr |
Specs reflect public information and early-access reports as of August 2026 and will be updated as official details land. Kling 3 and Seedance 2.0 are live on Tryonr today; Flux 3 and Seedance 2.5 open soon.
The multi-modal design opens formats that used to need three separate tools.
Chain multi-shot sequences with dialogue into complete scenes — one prompt per beat, audio included, no separate edit for sound.
Early testers found Flux 3 exceptional at period footage — '90s classrooms, vintage interviews and documentary-style scenes that feel authentically dated.
Product shots that move, speak and sound right for the brand, generated as one clip instead of a video plus a voiceover plus a mix.
Vertical, dialogue-driven clips for TikTok, Reels and Shorts — characters that rant, react and joke straight from a text idea.
The clearest look at Flux 3 today comes from Black Forest Labs' own announcement thread and the public previews that followed — multi-shot short films, dialogue scenes and style tests, straight from the source.
We keep this page free of fake samples: every clip shown on Tryonr will be generated by the model it is labeled with. Real Flux 3 showcases land here the day our access opens.
External links open the official Black Forest Labs posts on X.
Quick answers on availability, features and how to be ready.
Flux 3 was announced on July 23, 2026, and video generation is in early access. Access widens in waves through Black Forest Labs and partner previews; a full public release date has not been announced. Save your prompt on Tryonr to be ready when a window opens.
Flux 3 is Black Forest Labs' multi-modal AI model — one unified architecture that generates video, image and audio, and even predicts actions. It follows the FLUX image models but extends them into moving, sounding scenes.
Yes. Audio is generated natively with the video, including character dialogue. Early testers report convincing speech from very loose prompts, with lips and delivery matching the scene.
Early access shows up to 20 seconds per generation, across multiple shots from a single prompt. Longer formats may come as the rollout matures.
Early access has been limited and partly free through official previews. Pricing for full access hasn't been announced. On Tryonr, saving your Flux 3 prompt is free today, and generation will use Tryonr credits once live.
Flux 2 generates still images. Flux 3 adds video, audio and action prediction in one jointly trained model — so a prompt can produce a finished, sounding clip instead of a frame.
They aim at different jobs: Flux 3 leads on multi-modal realism and dialogue; Seedance 2.5 pushes native 4K and 30-second single shots. Compare both on Tryonr and pick per project — see our Seedance 2.5 page for its specs.
We're preparing Flux 3 generation and will connect it as soon as API access allows. Until then, the complete Seedance 2.0 generator is available directly on this page, with every result clearly labeled.
Use the live Seedance 2.0 generator on this page today. Flux 3 will be connected here first when its API opens.
No redirect · Every output is labeled with the real model
Compare the new wave of models or start generating right now.